On 15 September 2026, a company called TypeSafe released a model named Jev that did something unusual: instead of writing an answer, it returned a value chosen from a list of options supplied with the question.
In the three weeks that followed, Cloudflare released Clef, Amazon’s Strands Labs open-sourced Strands Decider 2B, OpenAI opened a Decisions API in public beta, and on 9 October Microsoft launched Decision-1 in Foundry with a personal endorsement from Satya Nadella.
Six entrants. Three weeks. Four of them hyperscalers.
When Microsoft, Amazon, OpenAI and Cloudflare all ship the same category of product within a month, the interesting question is not which one is best. It is what they all noticed at the same time.
What they noticed is that most of what is sent to a frontier model is not a request for prose. It is a request for a choice. Is this in scope. Does this need second-line review. Which of these queues, which of client intents, which of those alerts or hits. These models take a fixed set of options and return a calibrated probability for each one. They do not generate text, and several of them charge nothing for output tokens, for the straightforward reason that there are none.
The benefit is larger than it sounds, and it is not a benchmark claim. Microsoft’s own Xbox Research team reported using Decision-1 to label more than 10,000 feedback items at over 14 times the speed and roughly 200 times lower cost than GPT-6 Sol, at competitive quality. The Copilot team reported comparable quality to GPT-5.6 Luna at around 100 times the speed. Those are internal production workloads, not evaluation sets and they are also Microsoft’s own deployment, as is every speed and cost figure published in this category. They establish a direction, not a ranking.
Pricing tells the same story from the other angle. Decision-1 and Jev both list $0.042 per million input tokens with output free while Cloudflare’s flash tier sits at $0.038. Amazon’s Strands Decider 2B is Apache 2.0, free, and answers in about 115 milliseconds on a consumer graphics card. A whole band of decision work has just repriced towards zero, and part of it now runs on hardware a team already owns.
Which brings the actual management question into view, and it is not a procurement question.
A price collapse you cannot route to is a price collapse that happens outside your organisation.
If dozens of processes each call one frontier model directly, because that is the approved model and the interface is known, then none of this reaches the cost base. The saving does not live in the unit price. It lives in the allocation, and allocation requires something in the architecture capable of deciding where a request goes. Most organisations do not have that. They have a default.
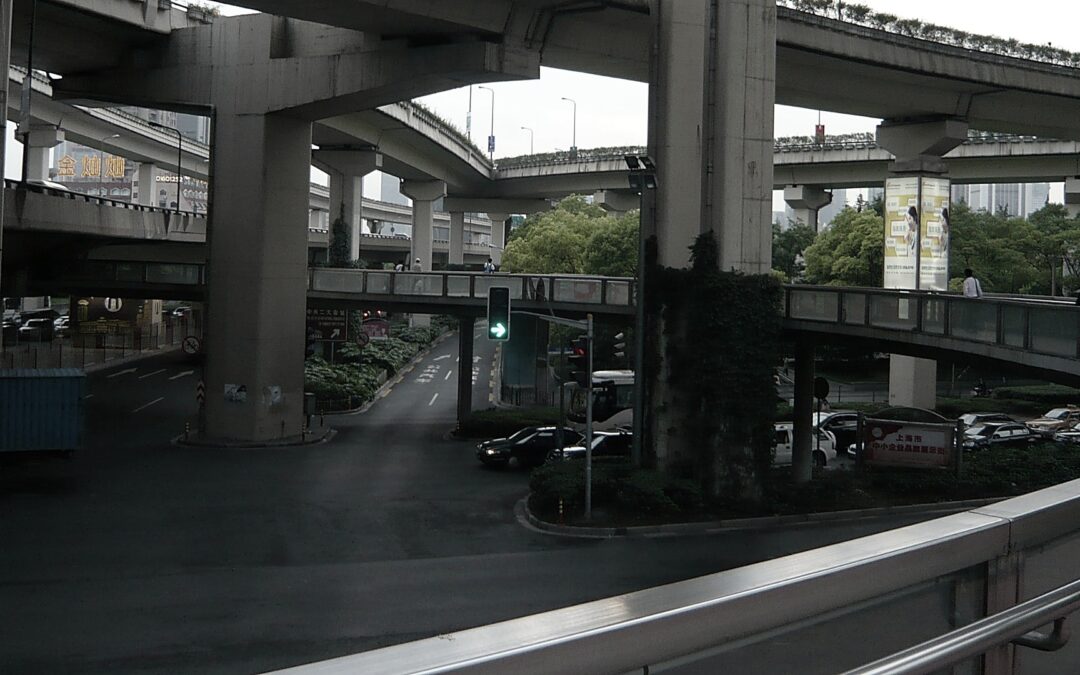
I spent a long time under a stacked interchange in Shanghai in 2007 (photo above), with a camera, trying to work out why something that complicated felt so calm. The answer is that no driver on it is ever asked to choose a level. The complexity sits in the structure, and what reaches the driver is a route already decided. An organisation where every process picks its own model has the complexity and none of the structure.
The missing piece has a name, and it is less complicated than it sounds. A routing layer is a step placed in front of your AI calls: it reads each incoming request and sends it to one model rather than another, according to rules you set.
What makes it work is that this step is nearly free to run. Deciding which model should handle a request means picking one option from a short list defined in advance which is precisely what these decision models do, in around two hundred milliseconds for a fraction of a cent. Run that same step on a frontier model and it consumes a meaningful share of the call it is choosing, which defeats the purpose. Built on the cheap tier, it disappears into the cost of whatever it routes to.
So the decision changes character. You stop choosing a model and start setting a policy. Choice-shaped work clears on the cheap tier. Work that genuinely needs prose or reasoning escalates. Low confidence escalates. The expensive model handles the minority of traffic that justifies it. That is where the cost curve bends, not in negotiating the price of a token, but in no longer sending the easy majority to a model built to write.
None of which is theoretical, and the proof predates the model class entirely. AT&T runs a routing layer across an internal AI estate processing some 45 billion tokens a day, assessing each task and sending it to the cheapest model that can handle it. On coding and comparable work, the company reported costs down by as much as 56% for a performance decline of around 2%, with roughly 40% of employee queries now served by open-weight models and a target of 60 to 70%. Those numbers come from routing between conventional generative models, the only option available at the time. The tier that arrived in September sits below all of them.
There is a precondition here that money does not buy. These models answer the question they are given, from the option set they are given — which means the cheap tier only pays if the decision is properly defined. An independent benchmark of Jev found this directly: on a phishing-detection task, breaking one badly framed question into its constituent decisions moved accuracy from 62.6% to 95.0%, with no change to the model. A model that writes hides this problem, because it produces plausible prose over a badly posed question and nobody notices the question was the issue. A model that returns a value does not hide it. So moving work down a tier exposes how well your own processes are actually specified, and that is internal work nobody procures.
Two things follow for anyone deciding how much to commit.
The first is that the interface is the durable asset, not the model. Jev and Decision-1 already share a request shape. Microsoft post-trained Decision-1 from Qwen3.5-9B and has said it intends to rebase it on other base models while keeping the API unchanged. Two of the six are Apache 2.0, one of them free and local. Build to the typed-decision contract and what sits behind it becomes a configuration change; build process logic around one vendor’s behaviour and roadmap and you are committed on the timescale of a rebuild. The contract is cheap to adopt now, while the category is competing on price.
The second is that a routing layer is a control before it is an optimisation, and this is the part that will reach a board before the savings do. I have argued elsewhere that the control point for unsanctioned AI use is identity rather than policy: who and what can reach which service. A routing layer is the complement almost nobody has: it governs where a request goes once it is already inside a sanctioned process. That is where an internal rule about which data may leave the organisation, and for which purpose, becomes something that executes and can be tested rather than something staff are asked to remember.
Here the economics and the control run in the same direction, which is rare enough to be worth noticing. A decision model that is free, open-weight and answers in 115 milliseconds on a graphics card a team already owns means a class of decisions can now be taken without the data reaching an external provider at all. The cheapest tier is also the one with no third-party exposure.
Two cautions come with it. The routing log becomes the only record of which model produced a given output. Once routing is dynamic, that is no longer answerable from the system design. And the layer fails quietly: a misrouted request does not error, it gets answered by the wrong model, and comes back as a clean, well-formed, confidently wrong value in a fraction of a second. Nothing in the output looks wrong, because there is no prose in which wrongness could show.
Both are addressable, the second more cheaply than people expect: the calibrated probability these models return is a control surface prose never offered, and a tier this cheap can afford to have a sample of its decisions checked continuously against the expensive one. You cannot alert on errors that do not error. You can watch the distribution.
The direction is what matters for planning. A category of cheap, fast, non-generative decision models arrived with four major platforms behind it in under a month, and the price of that work is converging towards the cost of hosting it. Organisations whose AI runs through a layer that can choose will absorb that as a step change in unit economics. Organisations where every process holds a direct line to one expensive model will read about it.
Which of those two describes your architecture?
Alexandre Castaing is Managing Director of Axon Advisory & Consulting, working with supervised financial entities in Luxembourg on digital transformation, AI governance and operational resilience. Articles are AI-assisted, human-directed, and source-verified.
#AIGovernance #AIArchitecture #FinOps #DORA #Luxembourg #DigitalResilience #BoardLeadership #CostOptimisation